Runs, turns, tools, outcomes
Use the framework-neutral Python SDK to record turns, tool actions, tests, retries, feedback, and explicit business outcomes. Parent-run links show relationships the application records.
Verdict records the work your agent actually performs and connects supported provider calls to that work. Its guided UI takes you from an issue or usage change to the affected run, a reviewed check, and ongoing monitoring.
Use the framework-neutral Python SDK to record turns, tool actions, tests, retries, feedback, and explicit business outcomes. Parent-run links show relationships the application records.
Supported Anthropic, OpenAI, and Google SDK entry points capture request and response metadata, latency, errors, and provider-reported token usage where supplied.
Import supported LLM telemetry, bounded text-only voice records, or local Claude Code and Codex history. Source gaps remain visible; unrelated records are not linked by guesswork.
Home shows what was captured and what needs attention. Suggested setup builds a source-aware plan. Investigation follows each finding to the recorded event.
See the screens →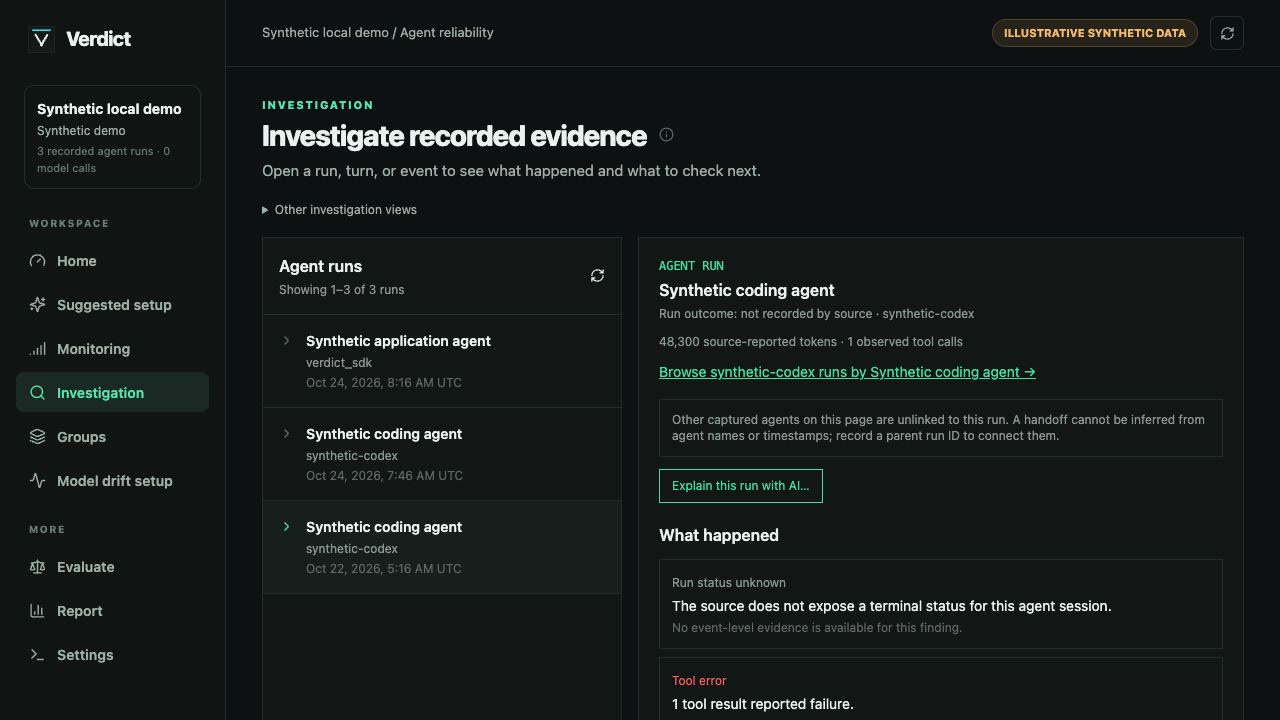
Deterministic analysis identifies captured tool and test failures and links to affected runs. Schedule recurring checks with a separate worker and verify its actual cycle status.
Preview bounded evidence for a day, session, run, turn, event, or supported call. A provider-backed judge is optional; compare candidate behavior on fixed reviewed cases.
Preview reference and current cohorts of eligible genuine model calls. Activate a reviewed policy only when its sample and measurement gates make sense. Statistical drift alerts apply to model calls.
Start with SQLite. For a shared deployment, use a dedicated PostgreSQL store, dashboard, and supervised monitoring worker. Producers can connect directly or write local spool files uploaded by the shipper to an authenticated collector.
Deployment responsibilities
Try Verdict on your own Claude Code or Codex sessions with no provider key and no source checkout.
python3.12 -m venv .venv
.venv/bin/python -m pip install --pre 'cognifity-verdict[dashboard]'
.venv/bin/verdict
Choose the detected local history in the setup screen, preview, and approve capture.
Instrument a Python agent with verdict.init() and agent_run(), or import a supported telemetry source. Use the full onboarding guide for provider extras and deployment topology.
python -m pip install --pre 'cognifity-verdict[anthropic,openai,google,dashboard,postgres]' cognifity-verdict-evalThe currently released packages are beta pre-releases, so these commands use --pre without hardcoding a version. Deterministic capture and investigation need no judge key.
Agree on the question, capture boundary, and success criteria before starting a POC.