Capture the work
Record application agent activity and supported provider calls, or import eligible telemetry and local Claude Code or Codex history.
Verdict connects agent runs, turns, tools, tests, and application outcomes to the model calls behind them. Investigate failures and token use, evaluate fixes, and detect drift in eligible provider model calls while watching agent activity over time.
Customer-managed · local-first · Apache 2.0 · optional bring-your-own-key evaluation
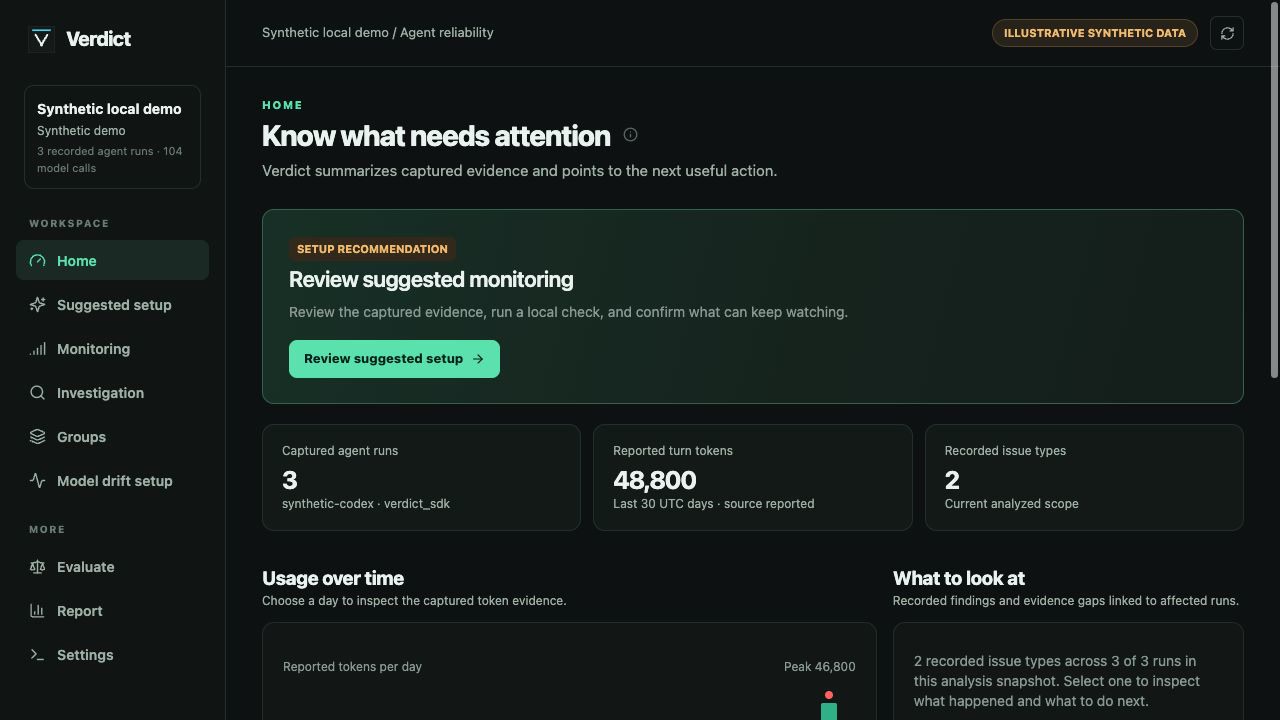
A model trace explains one call. An agent incident also needs the surrounding work: the turn, tool result, test, explicit outcome, and what changed after a fix.
Record application agent activity and supported provider calls, or import eligible telemetry and local Claude Code or Codex history.
Follow recorded issues and token usage into sessions, runs, turns, events, and genuine model-call traces. Coverage stays visible.
Evaluate selected evidence, compare reviewed cases, monitor recurring agent issues, and detect statistical drift in eligible provider model calls.
What failed? Open the recorded tool, test, provider, or application outcome behind a finding.
Where did usage go? Inspect reported tokens by day, session, turn, and eligible model call, with missing coverage labeled.
Did the change help? Compare a baseline and candidate on reviewed cases, then watch fresh evidence.
Is model behavior drifting? Review baseline and current cohorts of eligible provider model calls, then investigate statistical alerts alongside recorded agent issues.
Verdict uses SQLite for a local trial and dedicated PostgreSQL for a shared single-tenant installation. Python producers can write directly or spool bounded records for the shipper and authenticated collector.
See deployment options →Released beta paths
Claude Code and Codex imports are useful starting points, not the product boundary.
Explore the current UI using wholly synthetic data, then choose the evidence you would capture in your own environment.